Research / 02 / Knowledge refinement
DeepRefine
Knowledge that can be revised.
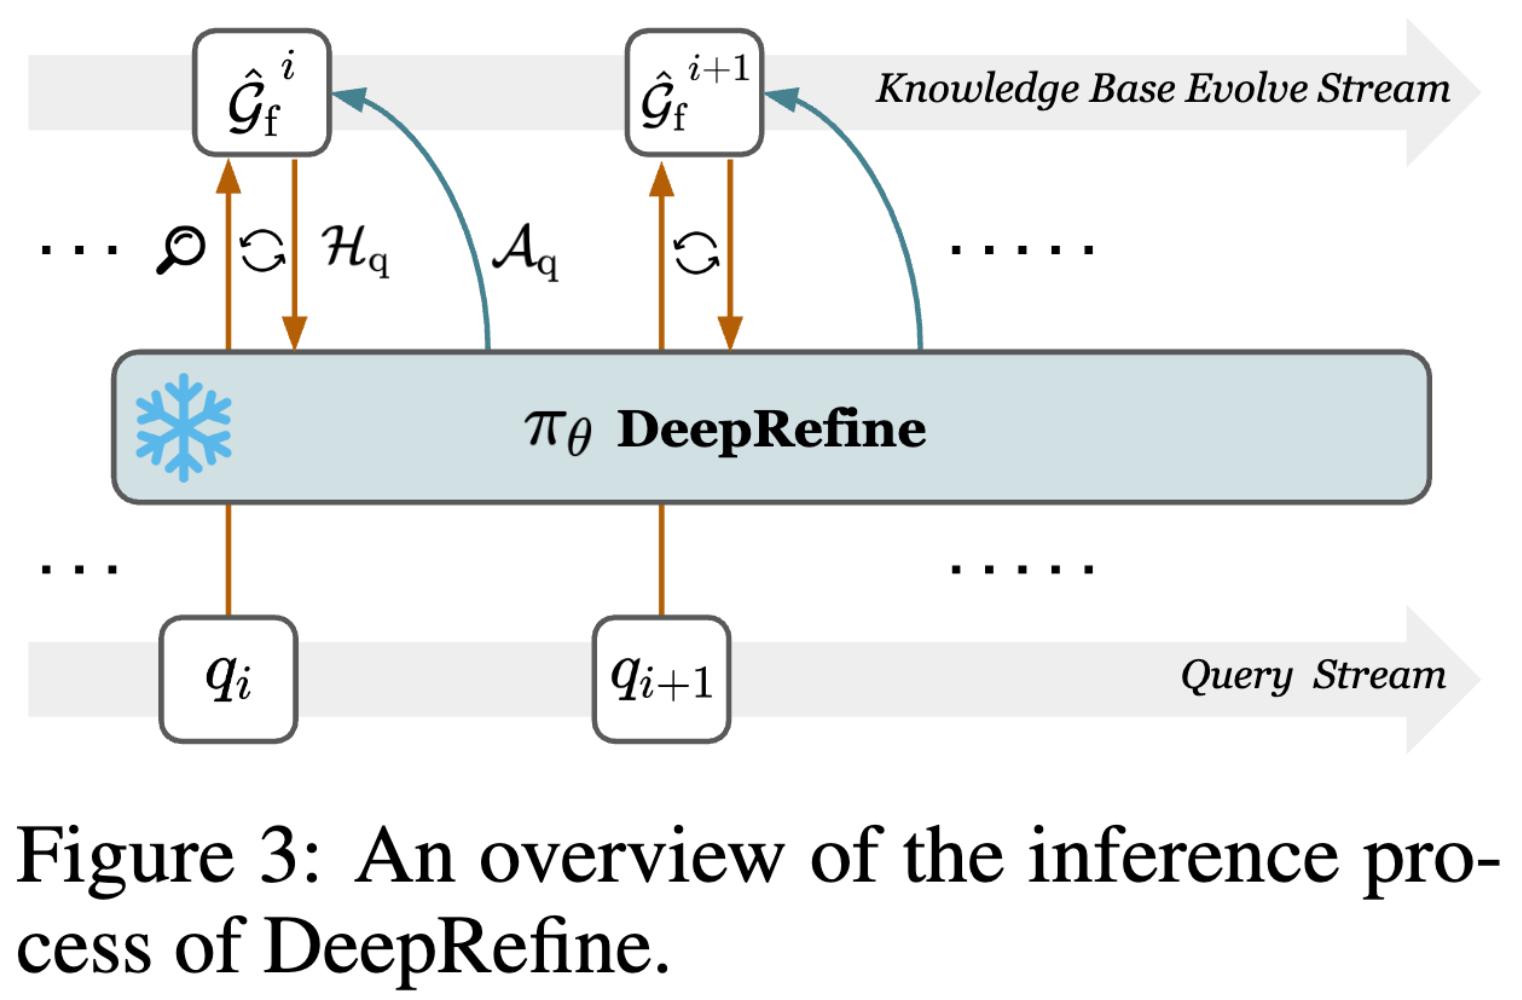
DeepRefine uses answerability checks, error diagnosis and refinement actions to update an existing knowledge base as questions arrive.
The research
What this work contributes.
Agent-built knowledge bases can contain missing evidence, inaccurate claims and redundant entries. DeepRefine uses the questions people ask to locate these defects and make targeted updates to the persistent knowledge store.
The method
How it works.
Check what can be answered
Interact with the knowledge base and assess whether retrieved evidence can support the current query.
Diagnose the gap
Use the interaction history to identify likely omissions, errors or redundant knowledge.
Refine the persistent store
Apply targeted actions. At inference time, the trained policy stays frozen while the knowledge base evolves.
Learned refinement, persistent improvements
Training uses a Gain-Beyond-Draft reward without gold references. The authors report downstream gains on retrieval-augmented generation and long-term conversation memory benchmarks.
Explore the studyConnection to finance
From research to financial intelligence.
Investment research depends on a knowledge base that improves as analysts use it. Questions about issuers, filings and product terms can expose gaps that ordinary retrieval leaves unresolved.
Maintaining investment research
Use recurring unanswered questions to identify missing links between filings, earnings commentary and issuer records, then propose focused repairs.
Improving institutional memory
Surface duplicate company entries or conflicting product descriptions for review, helping subsequent research conversations use a more coherent knowledge base.
Why do these two research notes disagree about the same issuer?
An illustrative workflow would inspect the retrieved notes, locate the conflicting claim and propose a source-backed correction. A financial implementation would retain dates, prior versions and reviewer approval for each accepted change.
These potential applications are our interpretation of the method. Financial outcomes are not evaluated in the cited work.
Paper & resources
Read the original work.
DeepRefine: Agent-Compiled Knowledge Refinement via Reinforcement Learning11 May 2026 · Research preprint · v1
This figure and summary refer to the May 2026 version. The August revision is titled DeepRefine: Agentic Knowledge Refinement via Reinforcement Learning. View latest version.